
A server fails during the working day, a network connection drops or a routine update breaks authentication. What happens next depends on decisions made long before the incident: which systems share dependencies, how traffic is redirected and whether the remaining infrastructure can carry the load.
For business leaders, resilient infrastructure is an investment in keeping essential operations available through disruption. For technical teams, it means understanding how failures develop and designing a controlled response. Buying additional hardware is part of that work, but the architecture must also account for application behaviour, data integrity and the people responsible for recovery. A useful starting point is to ask what the business must still be able to do when a component becomes unavailable.
Start with the service the business needs to preserve
An order-processing platform and an internal reporting tool rarely justify the same recovery investment. Before selecting redundancy or backup arrangements, agree which operations take priority, what interruption the business can tolerate and how much recent data it can afford to lose. Those decisions give infrastructure teams measurable objectives. They also establish whether temporary limitations are acceptable.
Customers might still be able to browse products while personalised recommendations are unavailable, whereas taking payment without reliably recording the order creates a different risk.
Document the minimum acceptable service during disruption, including performance and data consistency. This gives engineers a basis for deciding what should remain operational and what should stop safely.
Look for shared dependencies behind redundant components
Two application servers provide limited protection if both rely on one database, network switch or power distribution unit. The same problem appears across locations when otherwise separate environments share an identity service or an administrative account capable of changing both. Map dependencies from the customer-facing transaction down through application services, storage, networking and physical infrastructure. Include external services and the systems used to manage the environment. A failure in an administrative interface might leave applications running while preventing the team from making the changes needed to recover.
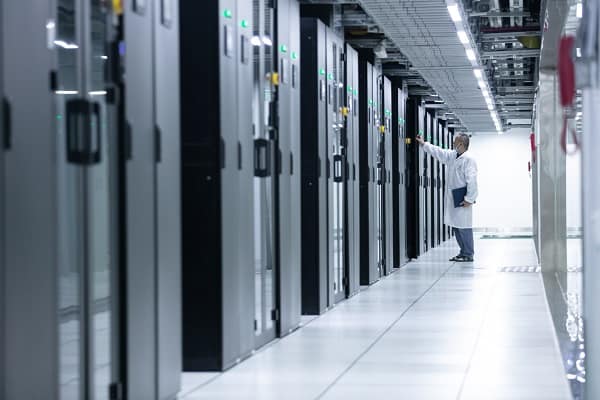
For businesses operating their own hardware, a solution such as M247 Global’s colocation service offers an alternative to running an in-house data centre. Colocation is a deployment model where your company rents physical space, power, cooling, and network connectivity in a third-party data centre to house and manage your own hardware. This is an option when access to supporting infrastructure is needed without building and operating the facility internally.
The deployment still needs to use that infrastructure correctly. Verify how servers connect to the available power feeds, whether network paths are physically diverse and which components remain shared. Facility resilience supports the architecture, while responsibility for hardware configuration and application recovery must be established separately.
Capacity also needs assessment under failure conditions. A cluster that comfortably handles traffic with every node available might become overloaded when one fails. Test the remaining capacity during expected peaks, allowing for the additional work created by failover and recovery.
Prevent a local problem from spreading
A slow dependency sometimes causes more disruption than a clean failure. Requests remain open, resources accumulate and other parts of the service begin to struggle. If several layers retry the same operation, the extra traffic increases pressure precisely when the system has the least capacity to absorb it. What you can do is set timeouts around the user operation and coordinate retry behaviour across components. Retries should be bounded and delayed, with safeguards against duplicating actions such as payments. Circuit breakers, which temporarily stop calls to a dependency that is repeatedly failing, give the affected service space to recover.
Queues and separate resource pools help contain pressure, provided their limits and recovery behaviour are understood. For example, moving non-urgent work into a queue protects an interactive service only if the backlog can later be processed without overwhelming it again.
Your business should also know what degraded operation looks like. Temporarily disabling an optional function is easier to manage when the decision, customer messaging and conditions for reactivation have already been agreed.
Make changes easier to reverse
Resilience needs to cover mistakes introduced by the organisation itself, as a faulty configuration deployed simultaneously to every redundant instance defeats the protection gained from running several copies. Use staged rollouts and health checks that measure application behaviour, before expanding a change. Keep a record of configuration changes, so responders can connect an emerging problem with a recent deployment.
Rollback procedures need testing, especially where database changes are involved. Reverting application code might leave it incompatible with a changed schema. Where rollback is unsafe, the team needs a tested recovery or forward-fix procedure and an explicit decision about who authorises it.
Test the failure and the response together
A failover test should demonstrate that the business service remains usable or returns within its agreed recovery objective. Seeing a standby server start is only one part of that evidence. Begin in a controlled environment, then expand the scope as the team gains confidence. Useful exercises include:
- Removing a node during representative load and checking performance on the remaining infrastructure
- Interrupting a dependency or network path and observing timeouts, retries and traffic redirection
- Restoring data and confirming that staff can complete the operations the business has prioritised
Record detection time, decision time and the point at which the service is validated. Include the people and suppliers who would participate in a real incident, with a substitute for key responders.
For cyber incidents, recovery must also establish that restored systems and data are suitable to reconnect. Replication alone offers limited protection against corruption or malicious changes copied from the primary environment, so protected backups and restoration tests remain necessary. Every exercise should produce assigned actions with deadlines. Once those changes are made, repeat the relevant test to confirm that the weakness has been addressed.
A resilient design gives failures a manageable outcome: essential work continues, optional functions are reduced where necessary, and recovery follows a procedure the team has practised. Investment decisions should therefore be tied to specific failure scenarios and evidence from testing. That helps your business direct its budget towards the dependencies and recovery capabilities on which continued operation actually relies.



Leave a Comment